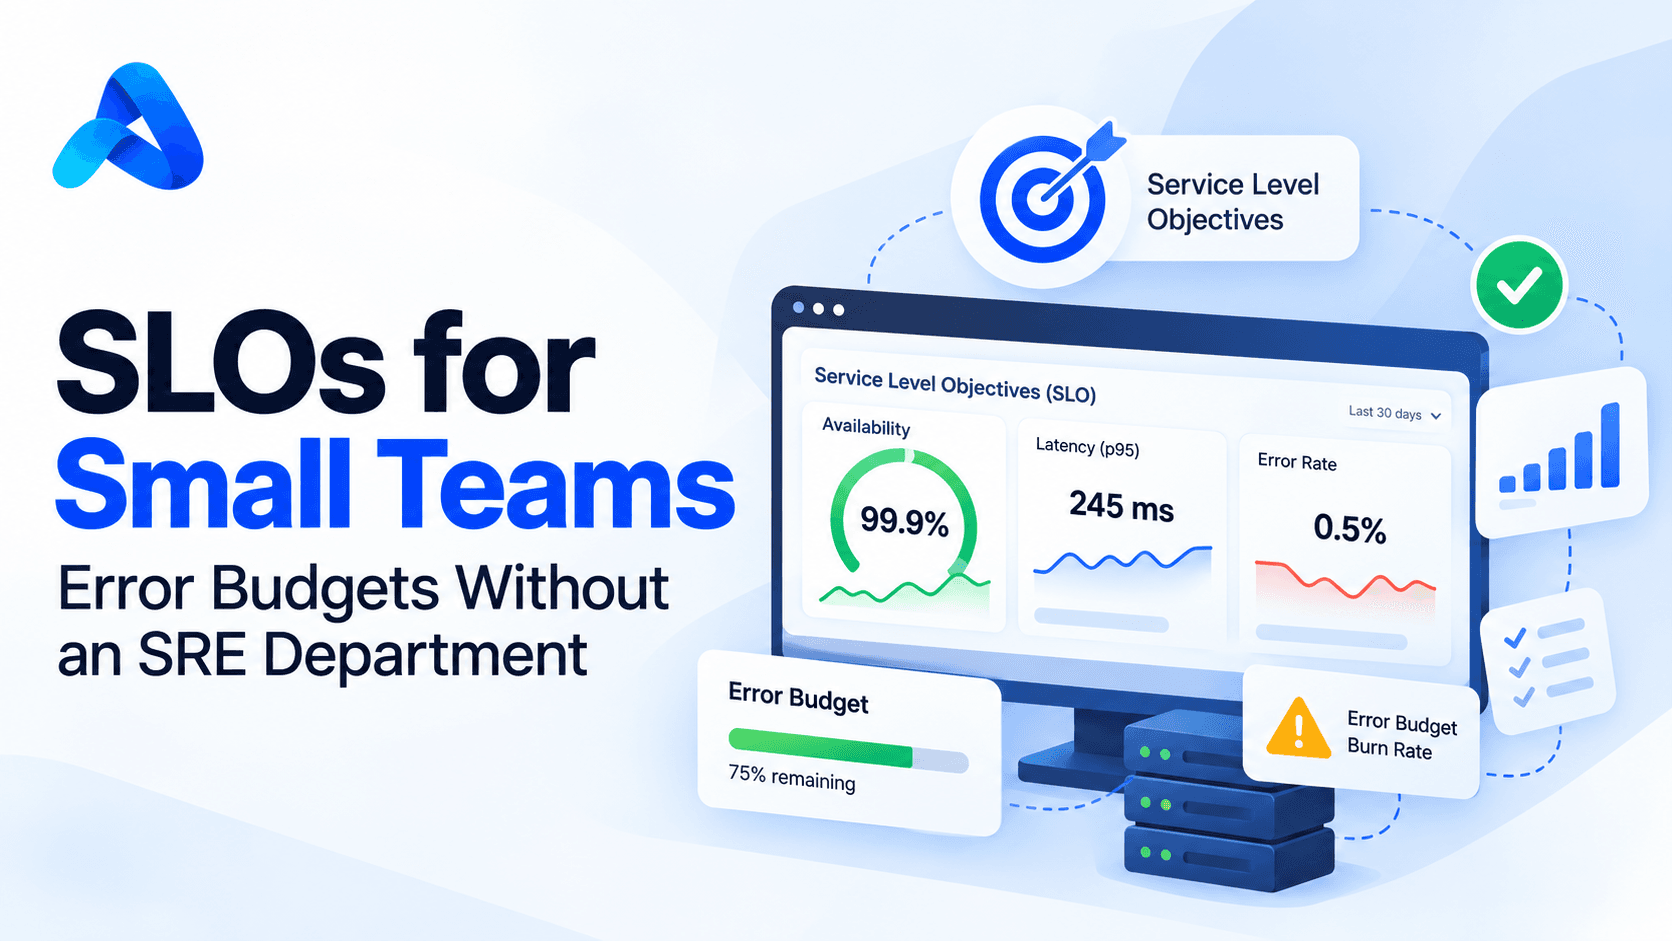
SLOs for Small Teams: Error Budgets Without an SRE Department
SLOs for small teams without an SRE department: choose SLIs that matter, turn targets into error budgets, alert on burn rate and agree a budget policy.
· 9 min read
Read articleArticles on metrics, logs and traces in production, and on keeping monitoring useful as systems and their telemetry grow.
2 articles · Latest
Observability is the ability to understand what a system is doing from the data it emits — metrics, logs and traces — so that problems can be found and explained, not just detected.
As systems grow, telemetry grows with them. Deciding what to collect, how to label it and what to keep is what keeps monitoring useful and its cost predictable.
Short answers to common questions in this area.
Understanding a system’s internal state from its telemetry — metrics, logs and traces — well enough to answer new questions about its behaviour.
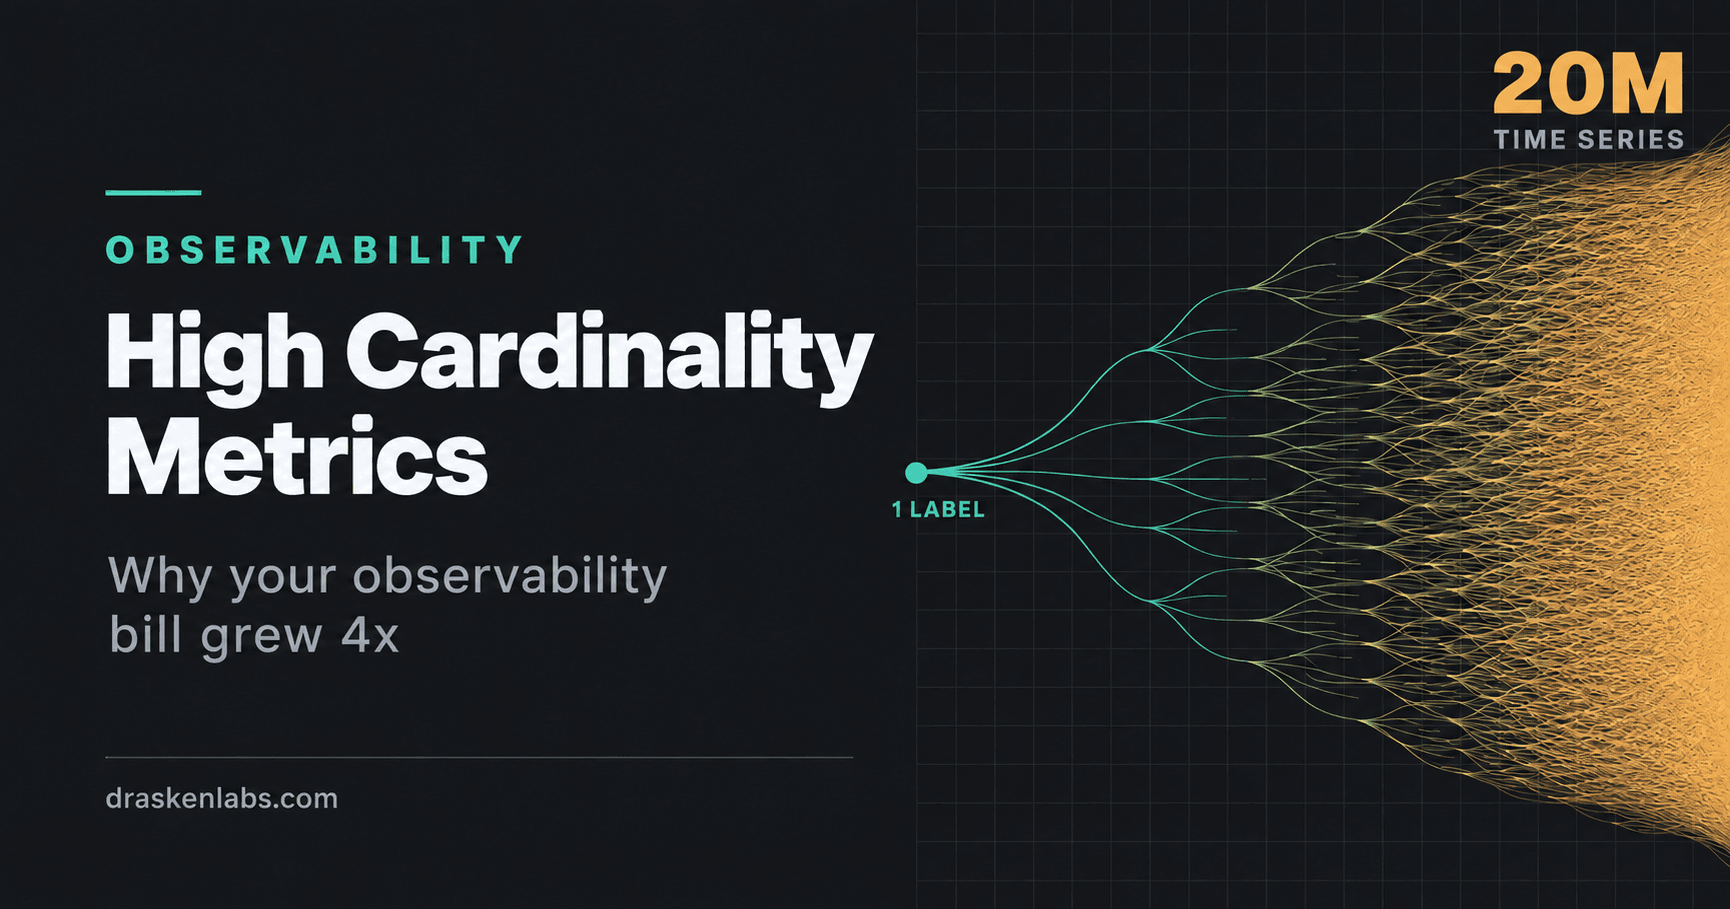
Metrics whose labels take very many unique values, such as user IDs or full request paths. Each combination becomes its own time series, which increases storage and cost.
High cardinality metricsAn open-source, vendor-neutral standard and set of tools for generating, collecting and exporting metrics, logs and traces.
Yes — metrics, logs, traces, dashboards and alerting for applications and infrastructure.
Observability